When I wrote The Machines That Need the CLI Most Belong to People Least Likely to Learn It, I put a wish in there: that someone would ship a quantized build once the 27B weights were out, and that a MOE version of the small model would follow. This is what happened next.
Last week I already said in my micro-notes what to watch:
What regular people should actually be watching is Qwen 3.8 27b, open weights next week. Quantize that one and it genuinely fits on our machines, with enough speed and enough intelligence for a local model. Waiting on unsloth.
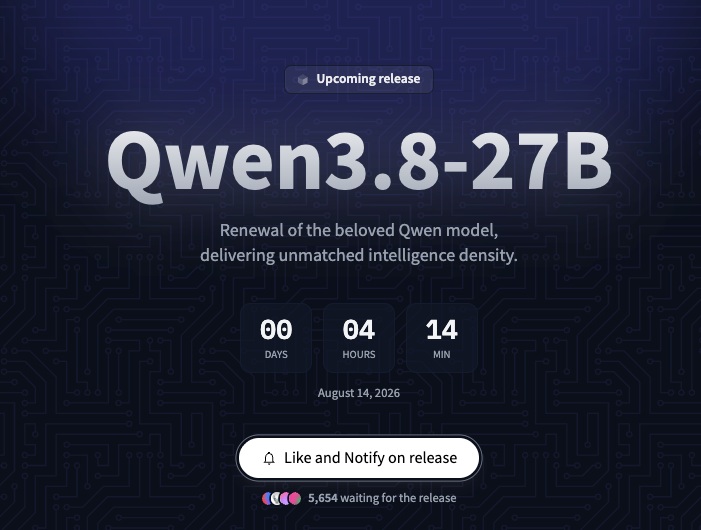
August 14, evening. The most exciting thing tonight: Qwen 3.8 27B is going open weights.
Background, for context. Two generations back, the 3.6 27B and the 35B A3B were the most usable small local LLMs I’d found on consumer hardware, and they still are. The Hugging Face model card is already up: native vision (images and up to an hour of video), switchable thinking mode and effort, 262K context, extendable to 1M!!!
Ran it the next morning. My take: it beat Sonnet 5, it beat Opus 4.7 and 4.8 (those two were regressions to begin with), and it’s about level with Opus 4.6 (though the official line is that it doesn’t beat it across the board). On the small-parameter local side, only Qwen gets past Qwen. Every other model has never lost a benchmark and never won a real task.
The only downside is that it’s slow, but I know this is my problem, not its problem. Someone asked me how the testing went and I gave the same answer: so far the only thing wrong with it is that it runs slow, and the capability jump is huge, but running slow is my problem, not its problem… I’m on an M4 Pro.
So I hope they ship an A3B too. A MOE version feels like it would be far more practical speed-wise.
Then at noon the same day, something moved: Qwen 3.8 35B A3B is actually happening. It’s already registered on Modelscope. Can’t wait, can’t wait, can’t wait.
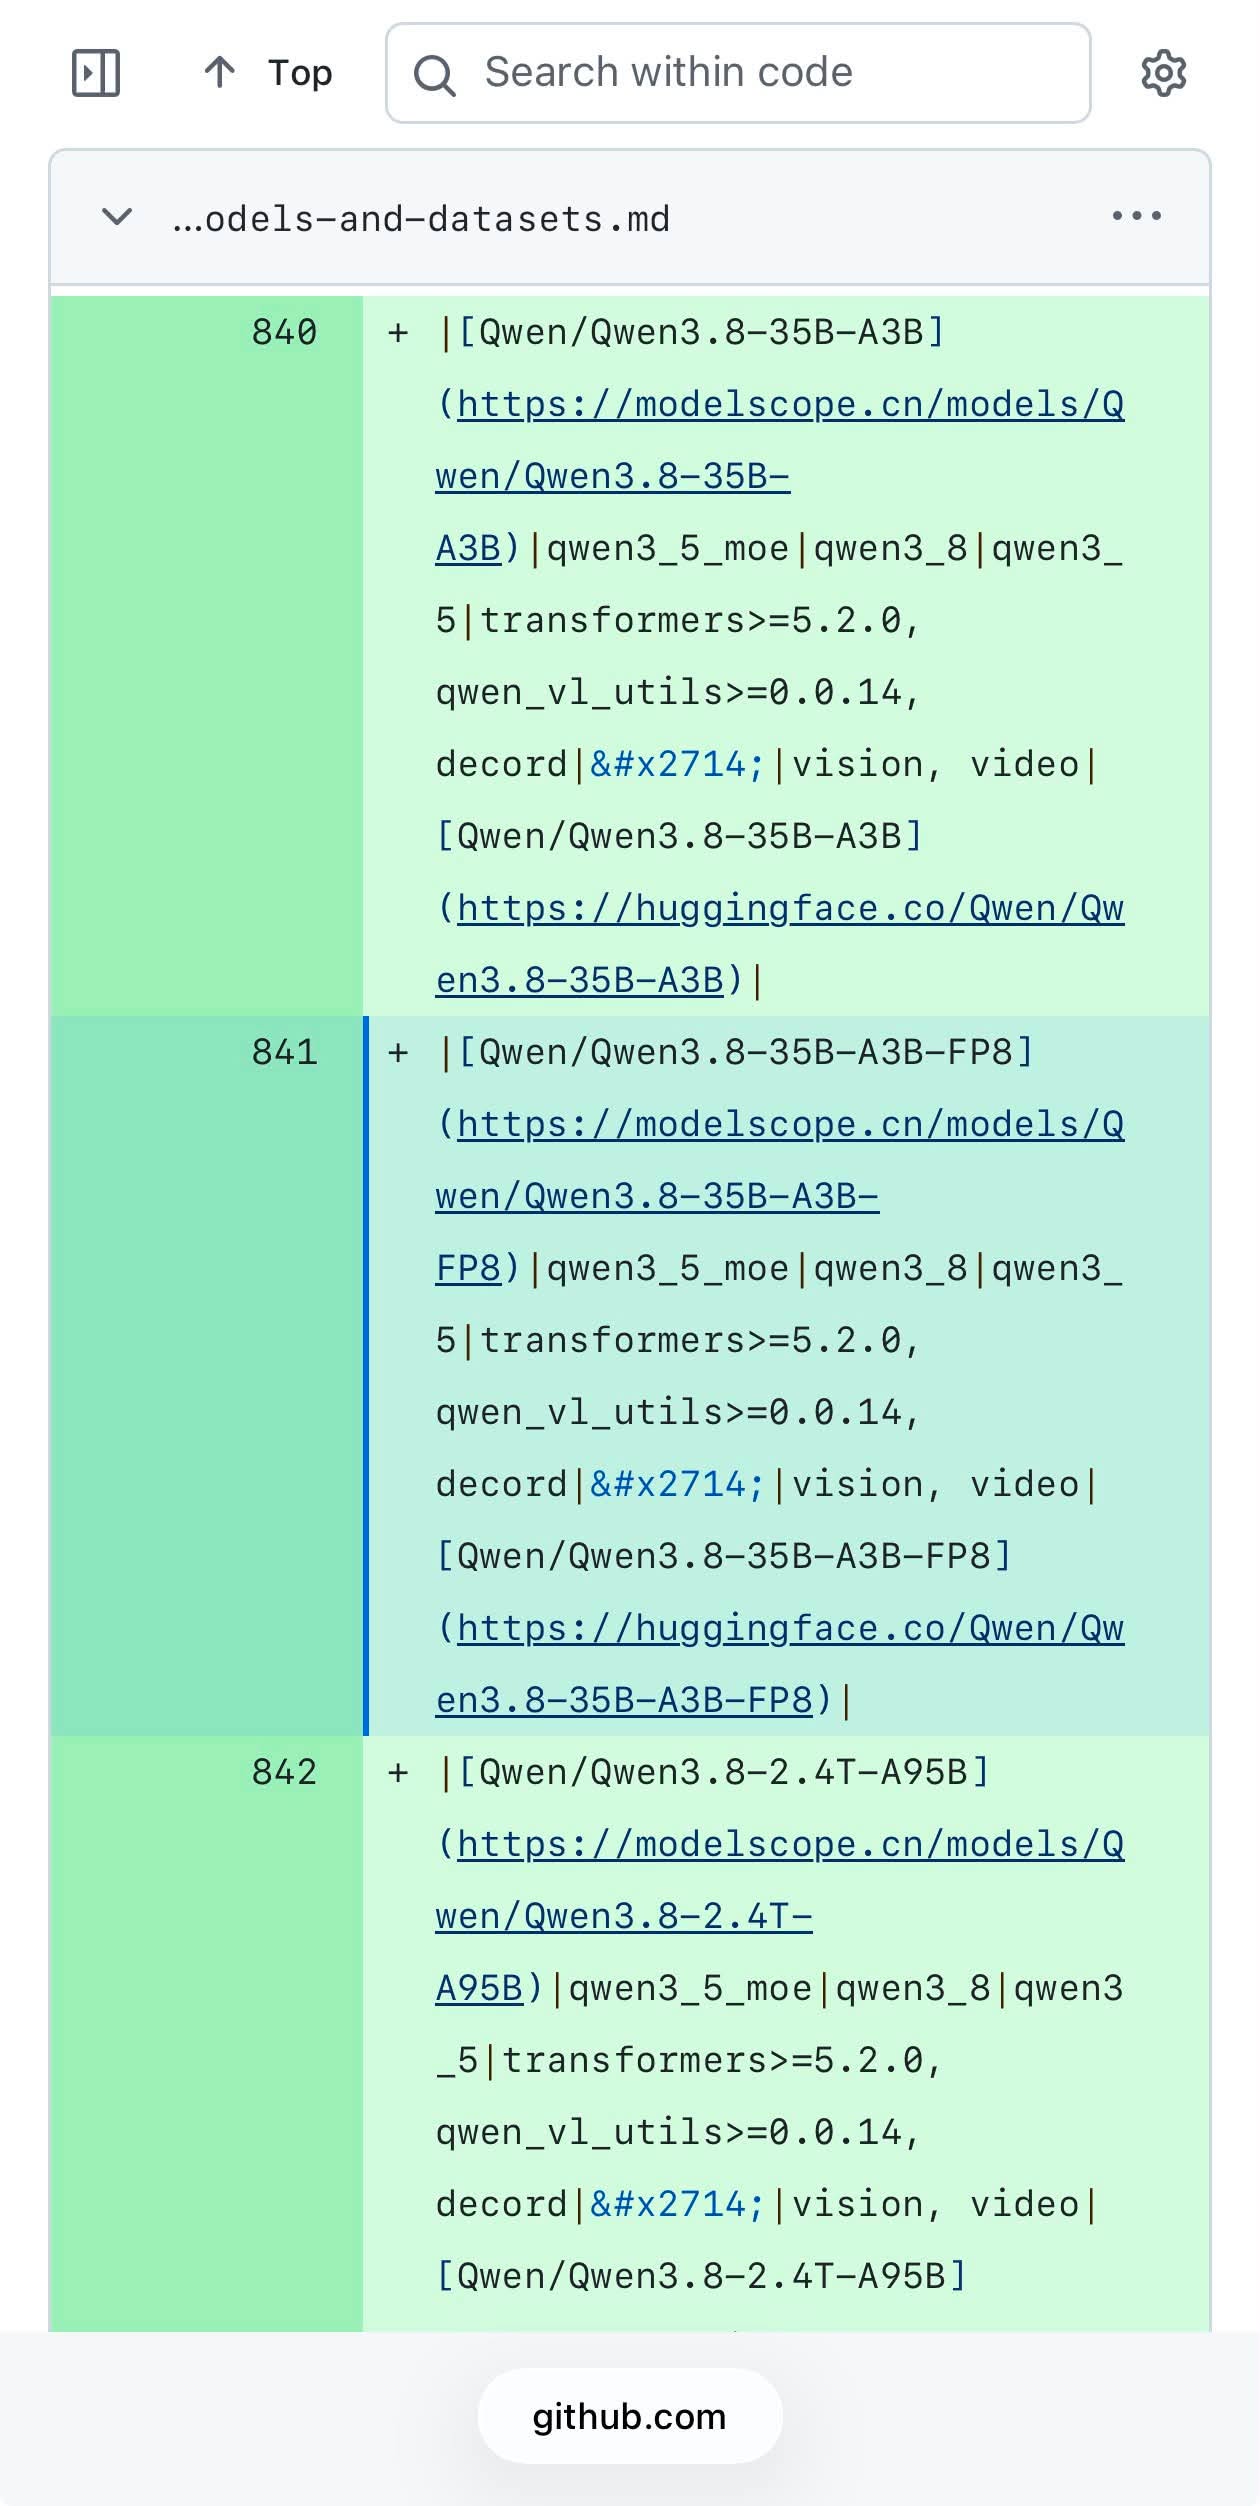
That afternoon someone posted a comparison to r/LocalLLaMA: same architecture, different weights.
Next morning, August 16: Qwen 3.8 35B A3B got deleted. Everyone can go home now.
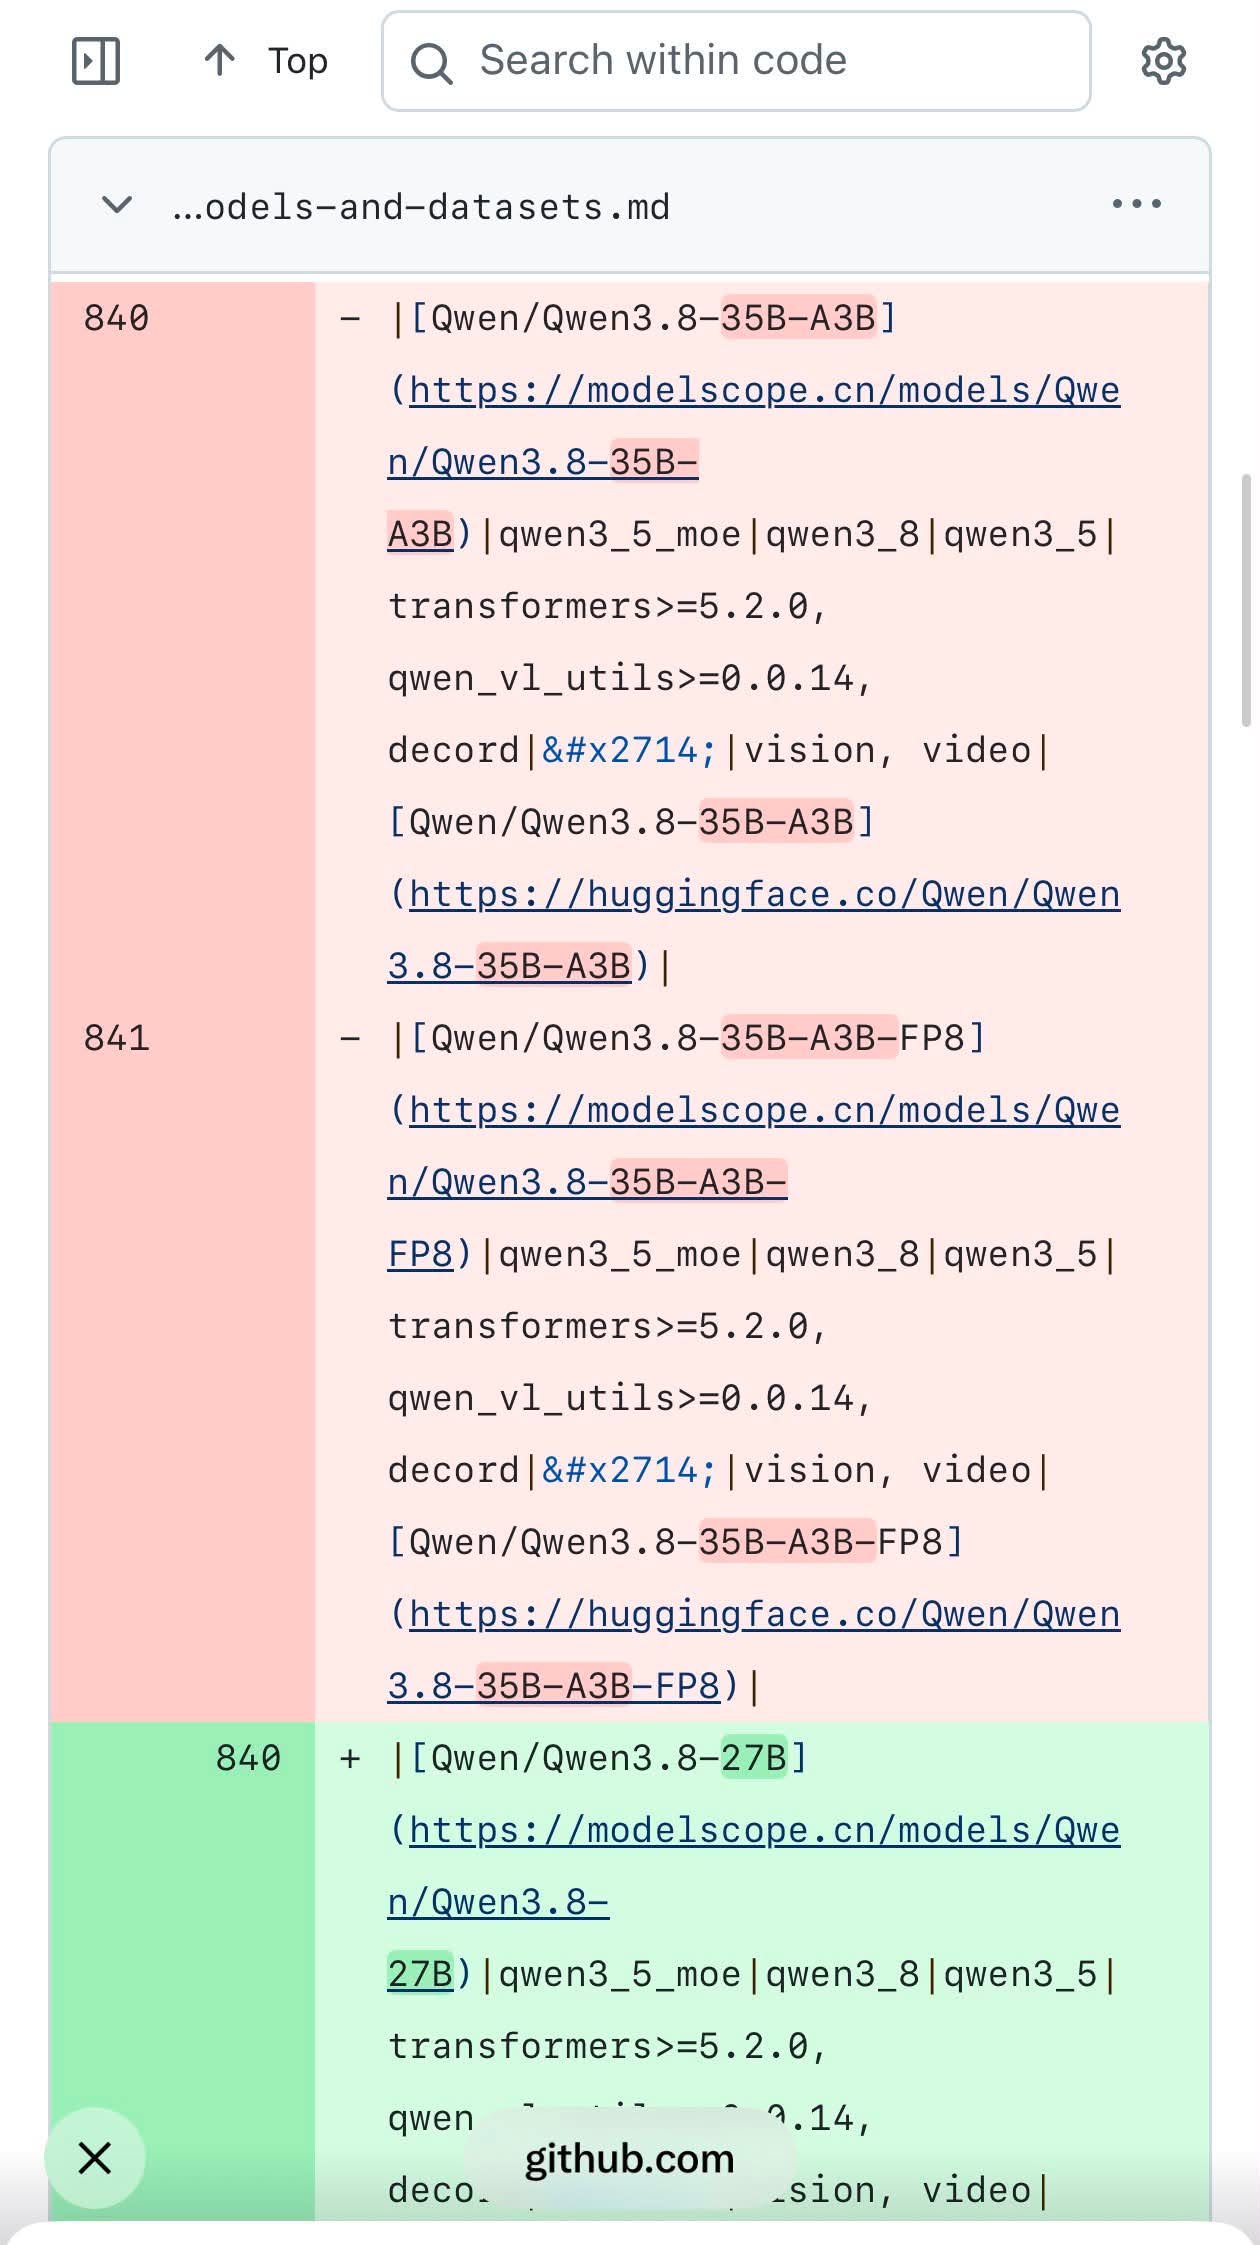
We need an a3b, a MOE like that.
Postscript: Qwen 3.8 Flash Next
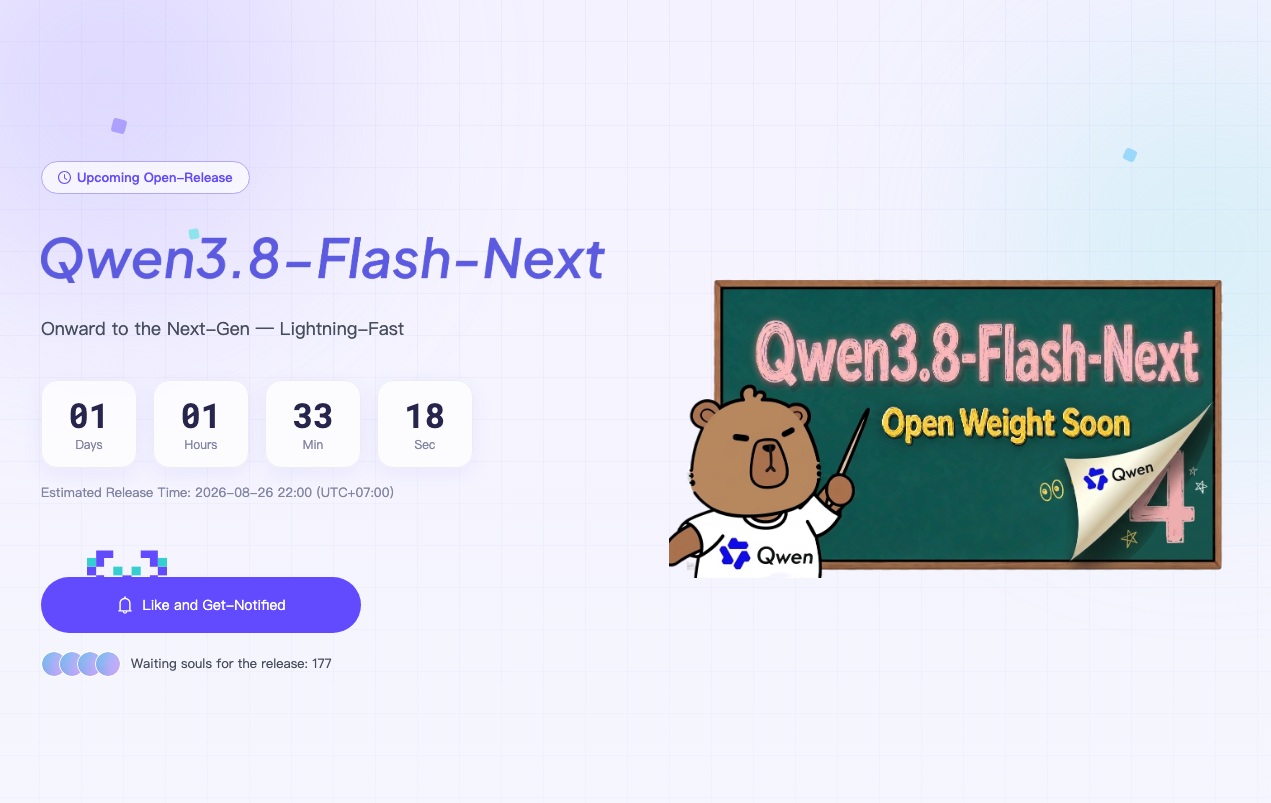
The evening of August 25, the sequel showed up.
Finally, an MoE Qwen 3.8 with open weights. And it’s on the new next-gen Qwen4 architecture. Word is this one is 125B A6B.
Let’s see whether it can properly take over from 3.6 35B A3B.