On this page
When do I call in Fable? The three moments that work best for me:
-
The main agent uses Fable for overall architecture planning, subagents do the implementation, and then it comes back to Fable for sign-off. (This is also the one most people recommend.)
-
The main agent runs on Opus or Sonnet, and when it gets stuck partway through, or I want an adversarial review or the thinking pushed wider, I call in a single Fable subagent as a one-off consultant. (This is the one I ended up using more.)
-
The weekly reset is tomorrow and there’s still a pile of quota left. (A\ isn’t getting one bit of that for free.)
Someone asked me the other day whether to turn on ultracode.
Why turn on ultracode (? Want to enjoy the feeling of ten thousand horses charging? Never mind that ultracode’s xhigh mode has an overthink problem on Opus 5. It wrestles with itself in its own head and just burns your tokens.
Turn ultracode off. Cap Opus 5 at med. Most subagents are fine on Sonnet. What matters is being clear about which point the smart model joins at: planning, coordination, on-call consultant, or sign-off.
Postscript: It Turned Into Two Modes a Week
This is funny. I’ve realized I’ve quietly turned into this:
Monday to Thursday: efficiency king, routine work running at full tilt (Sonnet plus the skills and pipelines I’ve already built, local models, 5.6 Luna/Gemini routing, and overnight automation on top).
Friday to Sunday: I suddenly notice I’ve been way too frugal the past few days and there’s a pile of quota left, so I open Fable and turn into creativity-explosion visionary mode, doing long-range exploration and planning for the future, tuning the harness, setting the guardrails.
Sunday 5pm: back to cowardly mode, and the cycle starts over.
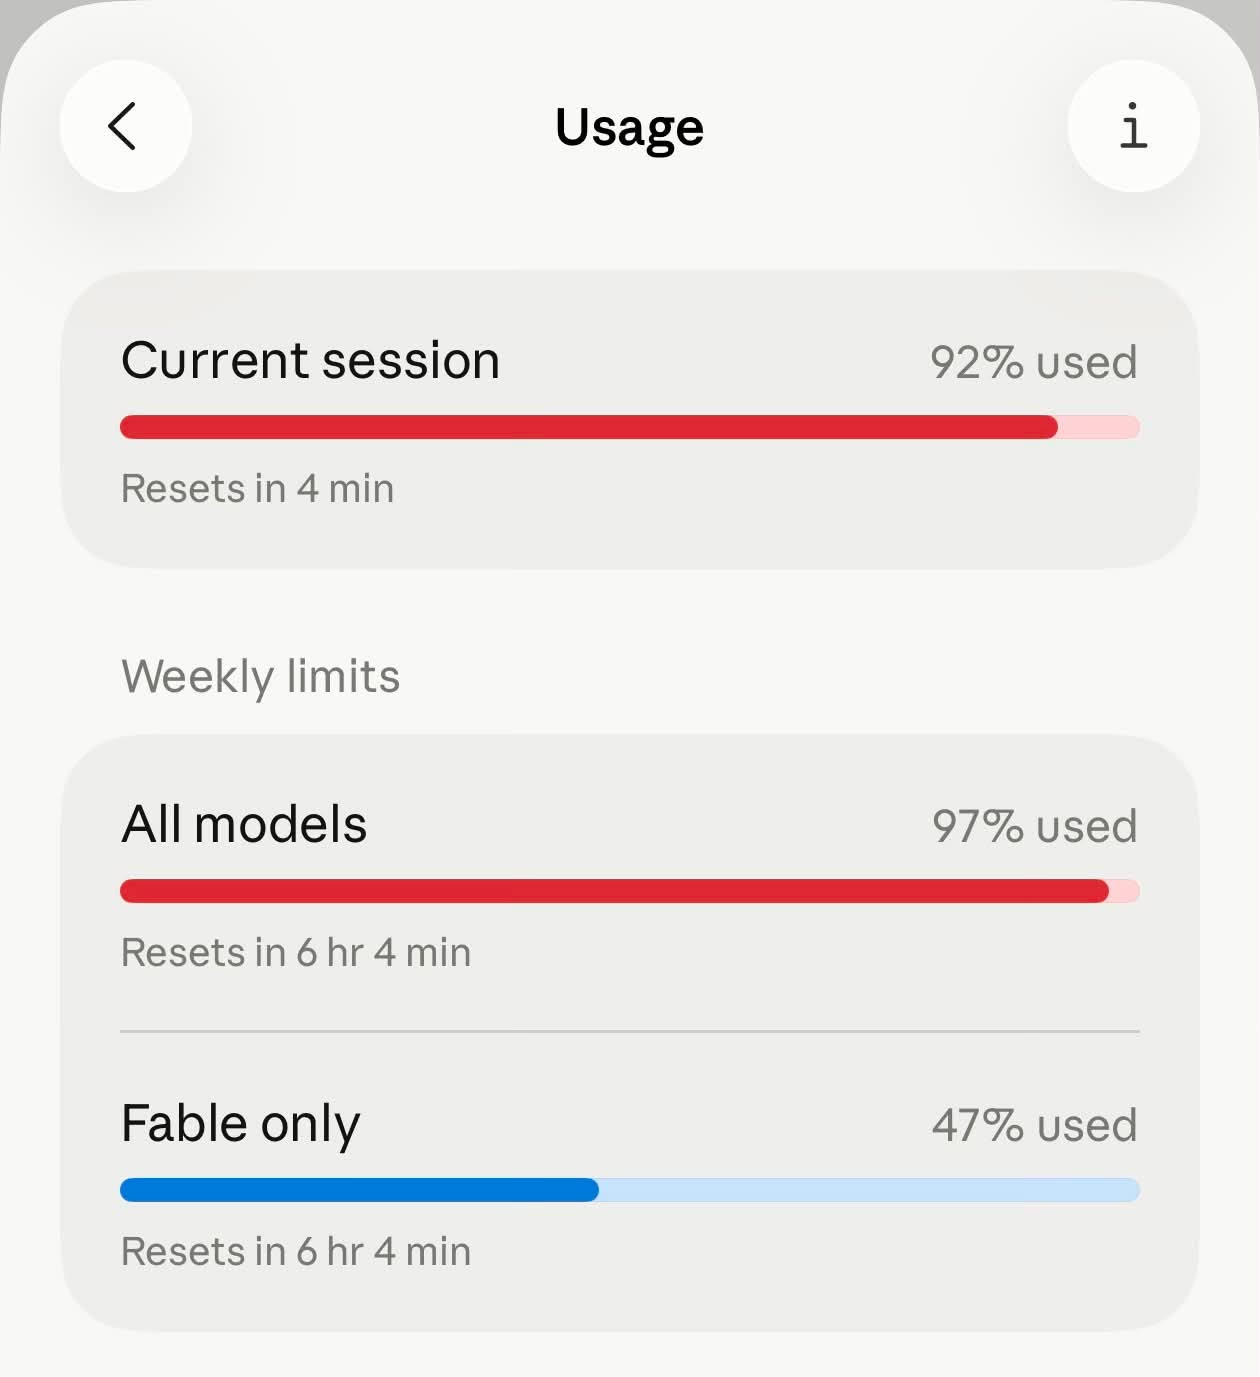
So my clients all reach me Monday to Thursday, and the new deliverables all ship Friday to Sunday.
Are you the same as me?
Postscript: Two Ways to Mix Models
Switching models means a cache miss, so the usual move is a subagent. When the path isn’t clear yet, run a smart main agent and hand the grunt work to cheap throwaway subagents. When the path is clear and only a few hard spots remain, flip it: cheap main agent, and call in a smart subagent as a one-off consultant or for sign-off.
Postscript: Two Hooks for Dispatching Subagents
Once, Fable dispatched three Fable subagents for me (no model specified, so they just inherited the main agent’s tier), and my quota was gone in an instant. Ever since then I’ve had this hook.
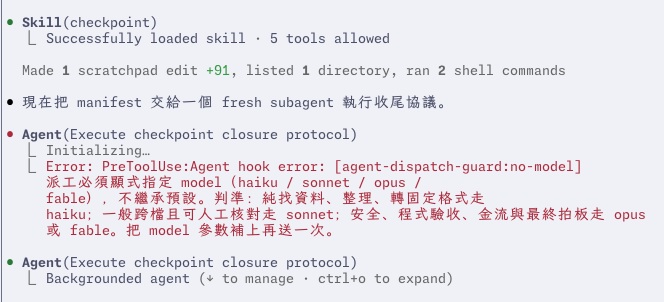
Want the same protection in your CC? Easy: copy this image, drop it into your CC, and tell it to set it up the same way.
Also, go into the settings and turn nested subagents off. Then I’d recommend a hook. Mine caps subagents at two at a time; at three or more, the hook stops and asks me Yes/No. In the dispatch section of my rules I also wrote that the default is two, and if it wants more it has to explain why.
Basically, manage them like employees: tell them what the rule is, and anything beyond it needs my sign-off.
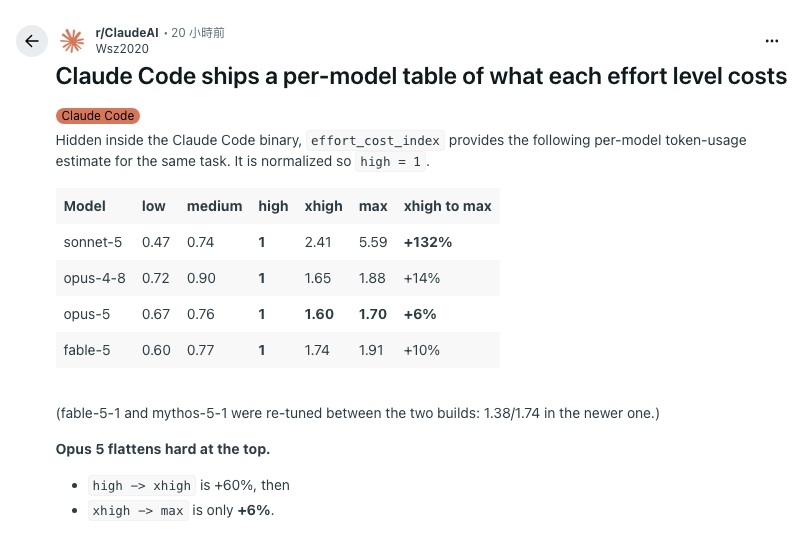
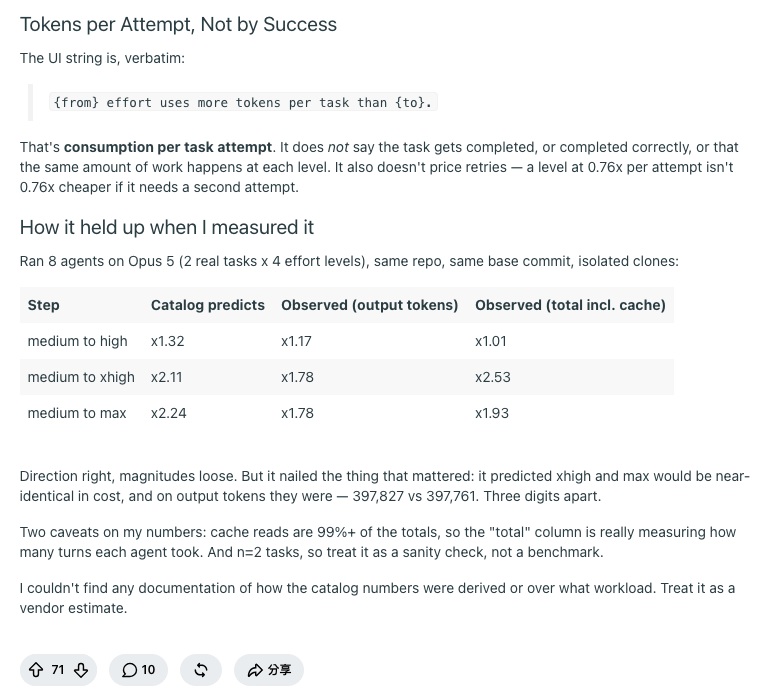
Postscript: What Each Step Up in Effort Costs
Someone on Reddit dug a per-model, per-effort token cost table out of Claude Code, then ran their own measurement (original post):